

Improved YOLO algorithm based on multi-scale object detection in haze weather scenarios AITranslate
Abstract AITranslate
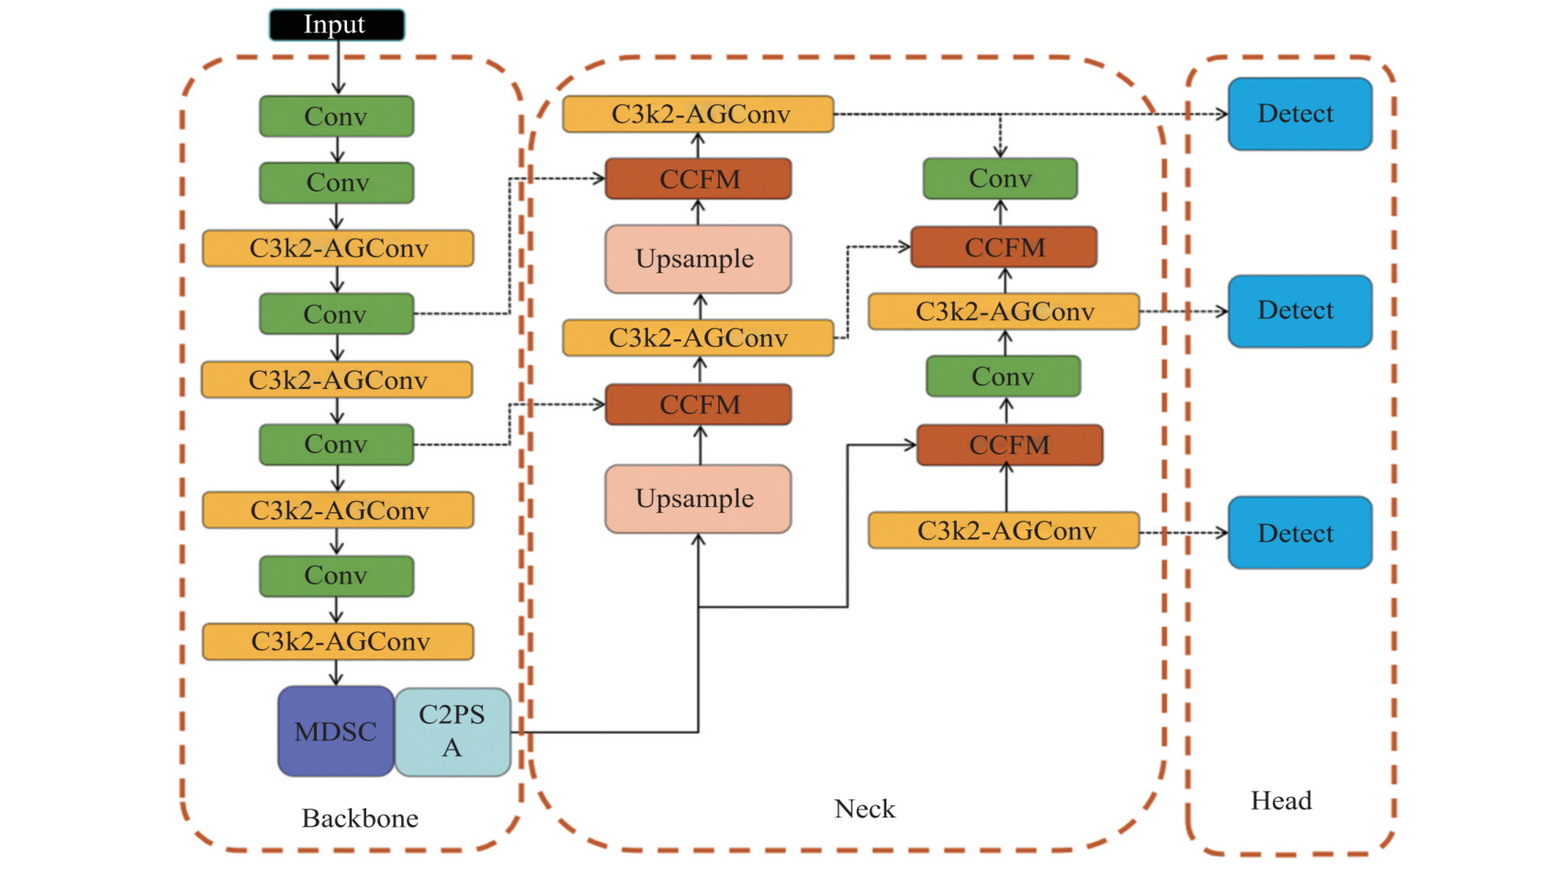
Computer vision-based traffic object detection plays a critical role in road traffic safety. Under hazy weather conditions, images captured by road monitoring systems exhibit three main challenges: significant scale variations, abundant background noise, and diverse perspectives. These factors lead to insufficient detection accuracy and limited real-time performance in object detection algorithms. We propose AMC-YOLO an improved YOLOv11-based traffic detection algorithm to address these challenges. In this work, we replace the C3k block's bottleneck module with our novel attention-gate convolution (AGConv), which improves contextual information capture, enhances feature extraction, and reduces computational redundancy. Additionally, we introduce the multi-dilation sharing convolution (MDSC) module to prevent feature information loss during pooling operations, enhancing the model's sensitivity to multi-scale features. We design a lightweight and efficient cross-channel feature fusion module (CCFM) for the path aggregation neck to adaptively adjust feature weights and optimize the model's overall performance. Experimental results demonstrate that AMC-YOLO achieves a 1.1% improvement in mAP@0.5 and a 2.7% increase in mAP@0.5:0.95 compared to YOLOv11n. On graphics processing unit (GPU) hardware, it achieves real-time performance at 376 (FPS) with only 2.6 million parameters, ensuring high-precision traffic detection while meeting deployment requirements on resource-constrained devices.
KeyWords AITranslate
[1]X. Zhao, L. Wang, Y. Zhang, X. Han, M. Deveci, and M. Parmar, "A review of convolutional neural networks in computer vision," Artificial Intelligence Review, vol. 57, no. 4, p. 99, 2024.
[2]R. Girshick, J. Donahue, T. Darrell, and J. Malik, "Rich feature hierarchies for accurate object detection and semantic segmentation," 2014 IEEE Conference on Computer Vision and Pattern Recognition, Columbus, H, USA, 23–28 June 2014, pp. 580–587.
[3]K. He, X. Zhang, S. Ren, and J. Sun, "Spatial pyramid pooling in deep convolutional networks for visual recognition," IEEE transactions on pattern analysis and machine intelligence, vol. 37, no. 9, pp. 1904–1916, 2015.
[4]J. Dai, Y. Li, K. He, and J. Sun, "R-FCN: Object detection via region-based fully convolutional networks," 30th Conference on Neural Information Processing Systems (NIPS 2016), Barcelona, Spain, 5–10 December 2016, pp. 379–387.
[5]J. Redmon, S. Divvala, R. Girshick, and A. Farhadi, "You only look once: Unified, real-time object detection," 2016 IEEE Conference on Computer Vision and Pattern Recognition, Las Vegas, NV, USA, 27–30 June 2016, pp. 779–788.
[6]W. Liu, D. Anguelov, D. Erhan, C. Szegedy, S. Reed, C.-Y. Fu, and A. C. Berg, "SSD: Single shot multibox detector," Computer Vision–ECCV 2016: 14th European Conference, Amsterdam, The Netherlands, 11–14 October 2016, Part I 14, Springer, 2016, pp. 21–37.
[7]T.-Y. Lin, P. Goyal, R. Girshick, K. He, and P. Doll´ar, "Focal loss for dense object detection," IEEE Transactions on Pattern Analysis and Machine Intelligence, vol. 40, pp. 2980–2988, 2018.
[8]A. Vaswani, N. Shazeer, N. Parmar, J. Uszkoreit, L. Jones, A. N. Gomez, Ł. Kaiser, and I. Polosukhin, "Attention is all you need," Advances in Neural Information Processing Systems, vol. 30, pp. 6000–6010, 2017.
[9]T. Zhang, L. Li, Y. Zhou, W. Liu, C. Qian, J.-N. Hwang, and X. Ji, "CAS-ViT: Convolutional additive self-attention Vision Transformers for efficient mobile applications," arXiv preprint arXiv:2408.03703, 2024.
[10]D. Shi, "Transnext: Robust foveal visual perception for vision transformers," 2024 IEEE/CVF Conference on Computer Vision and Pattern Recognition, Seattle, USA, 17–21 June 2024, pp. 17773–17783.
[11]J. Redmon and A. Farhadi, "Yolo9000: Better, faster, stronger," IEEE Conference on Computer Vision and Pattern Recognition, Honolulu, HI, USA, 21–26 July 2017, pp. 7263–7271.
[12]N. Li, M. Wang, G. Yang, B. Li, B. Yuan, and S. Xu, "DENS-YOLOv6: A small object detection model for garbage detection on water surface," Multimedia Tools and Applications, vol. 83, no. 18, pp. 55751–55771, 2024.
[13]J. Deng, W. Dong, R. Socher, L. -J. Li, K. Li, and L. Fei-Fei, "ImageNet: A large-scale hierarchical image database," 2009 IEEE Conference on Computer Vision and Pattern Recognition, Miami, FL, USA, 20–25 June 2009, pp. 248–255.
[14]N. Carion, F. Massa, G. Synnaeve, N. Usunier, A. Kirillov, and S. Zagoruyko, "End-to-end object detection with Transformers," in European Conference on Computer Vision, Springer, 2020, pp. 213–229.
[15]S. Cui and H. Deng, "PMG-DETR: Fast convergence of DETR with position-sensitive multi-scale attention and grouped queries," Pattern Analysis and Applications, vol. 27, no. 2, p. 58, 2024.
[16]Z. Liu, Y. Lin, Y. Cao, H. Hu, Y. Wei, Z. Zhang, S. Lin, and B. Guo, "Swin transformer: Hierarchical vision transformer using shifted windows," 2021 IEEE/CVF International Conference on Computer Vision, Montreal, QC, Canada, 10–17 October 2021, pp. 10 012–10 022.
[17]T.-Y. Lin, P. Doll'ar, R. Girshick, K. He, B. Hariharan, and S. Belongie, "Feature pyramid networks for object detection," 2017 IEEE Conference on Computer Vision Venice, Italy, 22–29 October 2017, pp. 2117–2125.
[18]J. Hu, L. Shen, and G. Sun, "Squeeze-and-excitation networks," 2018 IEEE conference on computer vision and pattern recognition, Salt Lake City, UT, USA, 18–23 June 2018, pp. 7132–7141.
[19]P. Wang, P. Chen, Y. Yuan, D. Liu, Z. Huang, X. Hou, and G. Cottrell, "Understanding convolution for semantic segmentation," 2018 IEEE Winter Conference on Applications of Computer Vision (WACV), Salt Lake City, UT, USA, 18–23 June 2018, pp. 1451–1460.
[20]S. Liu, L. Qi, H. Qin, J. Shi, and J. Jia, "Path aggregation network for instance segmentation," 2018 IEEE Conference on Computer Vision and Pattern Recognition, Salt Lake City, UT, USA, 18–23 June 2018, pp. 8759–8768.
[21]L. Tang, H. Zhang, H. Xu, and J. Ma, "Rethinking the necessity of image fusion in high-level vision tasks: A practical infrared and visible image fusion network based on progressive semantic injection and scene fidelity," Information Fusion, vol. 99, p. 101870, 2023.
[22]N. Yin, L. Shen, M. Wang, L. Lan, Z. Ma, C. Chen, X.-S. Hua, and X. Luo, "COCO: A coupled contrastive framework for unsupervised domain adaptive graph classification," 40th International Conference on Machine Learning, Honolulu Hawaii, USA, 23–29 July 2023, pp. 40 040–40 053.
[23]S. Ren, K. He, R. Girshick, and J. Sun, "Faster R-CNN: Towards real-time object detection with region proposal networks," IEEE Transactions on Pattern Analysis and Machine Intelligence, vol. 39, no. 6, pp. 1137–1149, 2016.
[24]Z. Cai and N. Vasconcelos, "Cascade r-CNN: High quality object detection and instance segmentation," IEEE Transactions on Pattern Analysis and Machine Intelligence, vol. 43, no. 5, pp. 1483–1498, 2019.
[25]Y. Zhao, W. Lv, S. Xu, J. Wei, G. Wang, Q. Dang, Y. Liu, and J. Chen, "DETRS beat yolos on real-time object detection," 2024 IEEE/CVF Conference on Computer Vision and Pattern Recognition, Seattle, USA, 17–21 June 2024, pp. 16965–16974.
Basic Information:
DOI:10.23919/CHAIN.2025.000008
Chinese Library Classification Number:
Citation Information:
Computer vision-based traffic object detection plays a critical role in road traffic safety. Under hazy weather conditions, images captured by road monitoring systems exhibit three main challenges: significant scale variations, abundant background noise, and diverse perspectives. These factors lead to insufficient detection accuracy and limited real-time performance in object detection algorithms. We propose AMC-YOLO an improved YOLOv11-based traffic detection algorithm to address these challenges. In this work, we replace the C3k block's bottleneck module with our novel attention-gate convolution (AGConv), which improves contextual information capture, enhances feature extraction, and reduces computational redundancy. Additionally, we introduce the multi-dilation sharing convolution (MDSC) module to prevent feature information loss during pooling operations, enhancing the model's sensitivity to multi-scale features. We design a lightweight and efficient cross-channel feature fusion module (CCFM) for the path aggregation neck to adaptively adjust feature weights and optimize the model's overall performance. Experimental results demonstrate that AMC-YOLO achieves a 1.1% improvement in mAP@0.5 and a 2.7% increase in mAP@0.5:0.95 compared to YOLOv11n. On graphics processing unit (GPU) hardware, it achieves real-time performance at 376 (FPS) with only 2.6 million parameters, ensuring high-precision traffic detection while meeting deployment requirements on resource-constrained devices.
quote
| GB/T 7714-2015 | [1] Junqing Shi, Sui Ruan, Yanhong Tao, et al. Improved YOLO algorithm based on multi-scale object detection in haze weather scenarios[J]. Chain, 2025, 2(2): 183-197. DOI:10.23919/CHAIN.2025.000008. |
| MLA | [1] Junqing Shi, et al., "Improved YOLO algorithm based on multi-scale object detection in haze weather scenarios." Chain, vol. 2, no. 2, 2025, pp. 183-197, https://doi.org/10.23919/CHAIN.2025.000008. |
| APA | [1] Junqing Shi, Sui Ruan, Yanhong Tao, Yingxu Rui, Jun Deng, Peng Liao, & Peng Mei. (2025). Improved YOLO algorithm based on multi-scale object detection in haze weather scenarios. Chain, 2(2), 183-197. https://doi.org/10.23919/CHAIN.2025.000008 |
| IEEE | [1] Junqing Shi, Sui Ruan, Yanhong Tao, Yingxu Rui, Jun Deng, Peng Liao, and Peng Mei, "Improved YOLO algorithm based on multi-scale object detection in haze weather scenarios," Chain, vol. 2, no. 2, pp. 183-197, 2025, doi: 10.23919/CHAIN.2025.000008. keywords: {convolutional network;object detection;self-attention mechanism;YOLO algorithm} |